Metronome.fm's voice control can now be started with a wake word. It works in desktop browsers when you turn on "Voice command with “Hey Friko”" in the menu (experimental). Say "Hey Friko" and you hear a chime, then you can ask for something like "tempo 120". The same model also responds to the English "Hey Friko". Friko is Metronome.fm's mascot character, named after furiko (振り子), the Japanese word for a metronome's pendulum (about the mascot).
Recognizing a wake word means keeping the microphone open the whole time. I didn't want to keep sending practice audio off the device, so I built a small model that runs on the device. This post covers how I collected the training data, and what worked and what didn't. Running it in the browser is covered in Running the "Hey Friko" wake word model in the browser without freezing the page, and turning the request after the wake word into a command in Turning voice requests into commands with Jev, while ignoring talk during practice.
Training only the classifier, with openWakeWord as the base
I compared two ready-made options for wake word detection.
- Picovoice Porcupine: You can create any wake word right away, and it supports Japanese. But the free tier appears to have ended on June 30, 2026, leaving only enterprise contracts
- openWakeWord: It turns audio into a mel spectrogram, passes it through Google's speech embedding model, and makes the final call with a small classifier per wake word. The first two models (the mel spectrogram conversion and the embedding) are licensed under Apache 2.0
I chose openWakeWord and decided to train only the last classifier myself. However, the official pretrained classifiers are CC BY-NC-SA (non-commercial). The negative data used by default in openWakeWord's training recipe (features of sounds that aren't the wake word, used as examples it shouldn't respond to; 17 GB) is listed as CC BY 4.0 in some places and CC BY-NC-SA 4.0 in others, and I couldn't confirm which is correct. Metronome.fm has a paid plan, so I used neither and trained the classifier only on data with clear licenses.
The classifier is a fully connected network that takes 16 frames of features (about 1.3 seconds) from the embedding model and returns the probability that the wake word has just been said. openWakeWord's training script depends on old packages (acoustics, torchaudio.info) that no longer work in a current environment, so I used only its feature extraction and rewrote the audio augmentation (next section) and the training myself.
The voices came from Gemini TTS
"Hey Friko" is a new phrase, so no recordings of it exist anywhere. I synthesized the wake word with Gemini TTS (gemini-3.8-flash-tts).
- 30 voices say it in 12 Japanese and 6 English speaking styles (quietly, quickly, sleepily, calling from across the room, and so on). The English "Hey Friko" is learned by the same model
- Each call says the phrase 8 to 16 times in a row, and the audio is split at the silences. Clips where two consecutive repetitions ran together and couldn't be split are dropped
- Each wake word clip is transcribed with Whisper, and only clips where both "hey" and "furiko" are heard are kept (366 of 485)
As examples it shouldn't respond to, confusable words (furiko on its own, written フリコ or 振り子, "Hey Siri", "hey Rico" and so on) and things you'd say to yourself while practicing were made with the same voices as the wake word. With different voices, the model might learn "synthetic voice means wake word".
There were 152 calls, about $0.7 at most. The problem was the rate limit, not the price: the Gemini API's Tier 1 allows only 100 calls a day. The lighter model (gemini-3.8-flash-lite-tts) has its own separate limit, so I used both.
The generated voices were augmented before training. I mixed in Metronome.fm's click sounds, room reverb (the RIRS_NOISES dataset) and noise, and varied the speed, pitch, volume and bandwidth. Each wake word is placed so that it ends near the end of a 2-second clip. As a side note, feature extraction ran at about 87 times real time on the CPU, so I didn't use a GPU.
Three measures with real human voices
Measuring only on synthetic speech wouldn't tell me whether it works on real human voices. So I built a web page for recording evaluation audio myself and set up three measures.
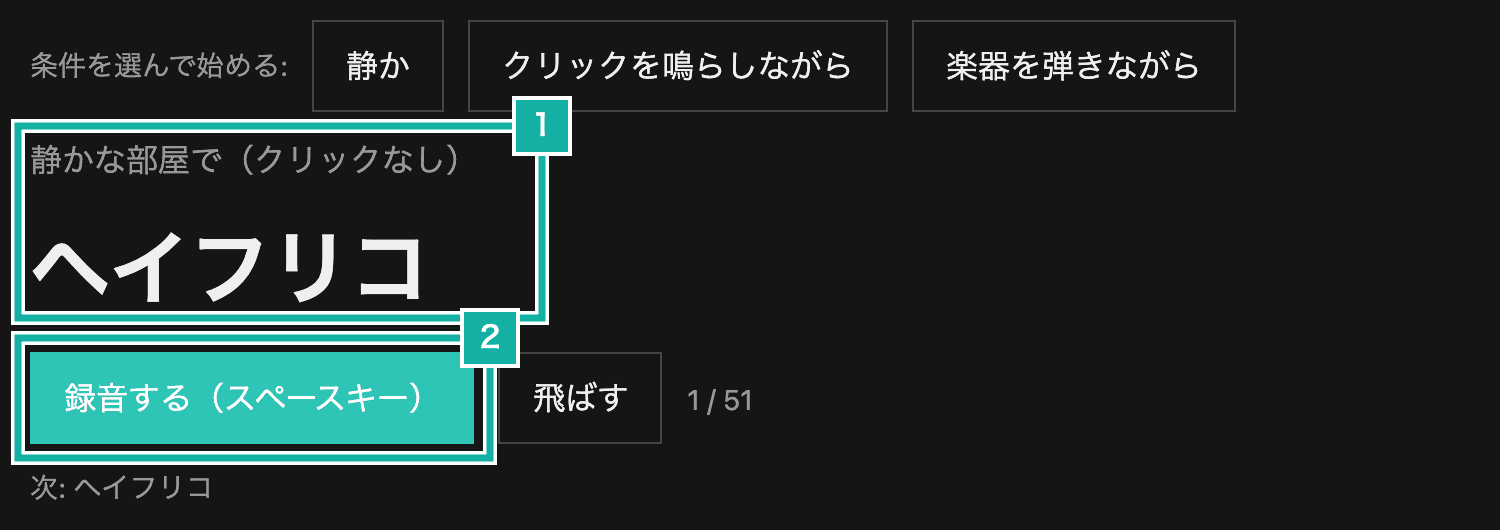
- The phrase to say and the condition (quiet, with clicks, while playing an instrument)
- Records 2.5 seconds with the space key
- Single takes: The wake word and confusable words, recorded 2.5 seconds at a time under three conditions: a quiet room, with the click playing, and while playing an instrument
- A continuous take: 305 seconds recorded in one go while the click played, while I played guitar and piano, and while background music and narration played. I said the wake word 33 times and pressed a key each time to record when I finished saying it
- 4 hours of Japanese YouTube audio: Held out from YODAS, a dataset of YouTube audio (more on it in a later section), and never used for training. Nobody says the wake word in it, so I count how many times per hour it falsely triggers
My own recordings are only for measuring and never mixed into training. Mixing them in would mean testing on voices the model was trained on, so the measurement would no longer be fair.
The first model triggered on "furiko" alone
The first model responded well to the wake word (92 to 100% on single takes). But it also triggered almost every time I said just "furiko" (フリコ or 振り子). It had learned the sound "furiko", not "hey" followed by "furiko".
First I added more voices of confusable words. In a quiet room, the rate at which it responded to confusable words dropped from 60% to 33%.
What helped more was taking the training wake word clips, cutting off the first 35 to 55%, and adding the result as negatives. That leaves only the "furiko" part, in the same voice and the same way of speaking, which lets the model learn that "furiko" only counts when it follows "hey". The rate dropped to 13%.
YODAS fixed false triggers on speech
The remaining false triggers were concentrated in the part of the continuous take with background music and narration. The audio used for training had almost no audio of people talking continuously. On the 4 hours of YouTube audio, it falsely triggered 79 times an hour.
So I added YODAS2, the second version of YODAS. It collects audio from YouTube videos published under Creative Commons licenses (licensed CC BY 3.0), with lots of narration, commentary, chatting and speech over music. I downloaded 20 hours from the Japanese part, used 16 hours as background audio for training, and held out 4 hours for evaluation.
YODAS includes timestamped transcripts for each video. I used them to find segments containing furiko (振り子) and similar words, and also cut those out as confusable words spoken by real people. But searching all of the Japanese data (278 GB worth) turned up only 54 segments, so I added the 4 files where the most such segments were found (40 hours of speech) to training as a whole.
Before YODAS | With 16 hours | With 56 hours (16 + 40) and segments, 3 models averaged | |
|---|---|---|---|
4 hours of YouTube: false triggers per hour | 79 | 8.1 | 3.8 |
Same, with a threshold of 0.95 | 37 | 2.0 | 0.3 |
Continuous take: wake words responded to | 88% | 85% | 82% |
Single takes: responses to furiko and similar in a quiet room | 13% | 18% | 7% |
The threshold is the probability above which the model counts it as the wake word (the app uses 0.5). The middle and right columns are averages over three training runs each. Only the right column was measured by averaging the probabilities of the three models from those three runs (see the next section).
Don't judge from a single training run
Along the way, I noticed how much each training run varies. With the same data and only the random seed changed, false triggers on the 4 hours of YouTube ranged from 6 to 10 an hour. The 6 I got when I first trained it only once was just a lucky run.
Since then, whenever I change the recipe, I train three times with different seeds and compare the averages. Compared that way, the recipe with the segments cut from YODAS triggered on furiko and similar words 7% of the time in all three runs, consistently lower than before (13 to 27%). In exchange, the rate of responding to wake words in the continuous take also dropped a little in all three runs (85% to 80%, averaged over the individual models).
Averaging the probabilities of the three models reduced the variation and cut false triggers to about half of a single model's. The file grows to 1.25 MB (three times about 400 KB), but the classifier is small, so detection takes hardly any more computation.
What didn't work
- Six times as many clipped clips, and three times the weight on confusable words: It didn't help with furiko in my own voice, and the response rate on the continuous take dropped too
- Adding my own recordings of furiko and similar words to training: As an experiment, I put some of the measurement recordings into training. Adding half of the 42 takes (21) changed almost nothing. They get buried among thousands of synthetic clips
- Voice enrollment: I enrolled 22 of my own wake words, and only when the base model triggers does a logistic regression decide whether it's my voice. Responses to confusable words dropped from about 10% to 3%, but the response rate on the continuous take dropped from 88% to 73%. It could become an opt-in feature, but I'm holding off for now
Next
False triggers on speech are now below once an hour with a threshold of 0.95. I haven't yet measured how many wake words in the continuous take it responds to at that threshold, though. Reducing triggers on furiko and similar words needs more confusable words spoken by real people. Next, I plan to ask family and friends to record some.